Microgravity can change how lenses form, glasses crystallize and particles assemble. The strongest evidence asks which physical process changed—and whether that change survives the journey from an experiment to a useful object.
A smooth surface can still belong to the wrong shape
A study released online on July 7, 2026 reported optical-lens experiments performed aboard the International Space Station in April 2022. Omer Luria and colleagues formed and cured polymer lenses and separately demonstrated a larger water lens. The accessible publisher manuscript is labeled an unedited article in press. Its results include exceptionally smooth surfaces alongside unexpected deformation in some cured lenses. That combination is more informative than a simple declaration that manufacturing in space produces better optics: a surface can be smooth at one scale while the component's overall shape fails another requirement. Luria and colleagues, ISS fluidic-shaping study
The date matters twice. A paper appearing in 2026 does not mean its experiment happened in 2026. And an experiment demonstrating an optical object does not establish a production line that reliably supplies finished components. Both distinctions are easy to lose when an orbital manufacturing story is compressed into a picture of something beautiful floating in a cabin.
The physical proposition behind microgravity manufacturing is narrower, and more interesting, than a magical improvement in material quality. Change the forces and transport processes acting during manufacture, and the material may follow a different path. Whether that path is useful depends on what is being made, how it is evaluated and what alternative process is available on Earth.
Consider an imaginary lens with an extremely smooth surface whose curvature is wrong for its intended instrument. It could produce an attractive reflection in a photograph yet focus at the wrong location. A second imaginary lens might have the correct broad curvature but undesirable small-scale surface structure. Calling one “higher quality” without identifying the property leaves the comparison incomplete.
An optical component therefore invites several separate questions. What shape was formed? What remained after solidification? How did the finished object behave when light passed through it? Which properties changed during handling or storage? These questions are not obstacles invented to diminish a demonstration. They are the route from an interesting formation process to an object someone can use.
The same reasoning travels beyond lenses. A long fiber is not necessarily a low-loss fiber. A large crystal is not necessarily the best crystal for a particular measurement. A returned specimen is not necessarily representative of every specimen made. Space provides an unusual processing environment, not a universal adjective meaning superior.
Falling is not the absence of physics
The apparent weightlessness of an orbiting laboratory comes from its shared free fall with the objects inside it, not the disappearance of Earth's gravity. NASA's explanation of microgravity makes that distinction explicit. An object still has mass, and forces other than the common gravitational acceleration can still change its motion. The useful question for a manufacturing experiment is how the material moves relative to its container and apparatus. NASA, what microgravity means
NASA's researcher-guide introduction, published in July 2016 for a November 2015 edition, also distinguishes quasi-steady, vibratory and transient disturbances aboard the station. It identifies sources including equipment, vehicle operations and crew activity. This is an institutional description of the experimental environment, not a claim that every sample experiences the same acceleration history. “On the ISS” is a location; it is not a complete specification of the conditions at a particular experiment. NASA's acceleration-environment guide introduction
For an imagined comparison, two samples could spend the same number of hours in orbit while experiencing different disturbances during the minutes when their structures become fixed. A brief event before a liquid is prepared may have little relevance to the final object. An event during a sensitive stage may deserve closer examination. The total time in space does not identify which history occurred.
This makes the material's timeline a better organizing device than a mission badge. Preparation, transport, activation, processing, storage and recovery can each contribute to the final specimen. An observed difference is a result of that complete history until an experiment separates the contributions more precisely.
The word “microgravity” can also conceal differences between research platforms. A short interval in an aircraft, a longer interval in a spacecraft and an Earth-based technique that suppresses one gravity-related mechanism are not interchangeable environments. Each can answer a useful question. The mistake is to assume that success in one automatically validates every stage that another would have to support.
A careful report therefore identifies the physical feature it is trying to change. Is the purpose to reduce settling, alter buoyancy-driven flow, remove contact with a container, or allow surface forces to determine a shape? Those are different interventions. Some can be approximated on Earth for a particular task; others require a different experiment. The name of the environment alone does not establish the cause of the outcome.
The terrestrial alternative is part of the experiment
Valeri Frumkin and Moran Bercovici's 2021 fluidic-shaping paper is a useful starting point precisely because its demonstrations were terrestrial. The method used an immersion liquid to balance the density of an optical liquid, allowing interfacial forces and boundaries to shape the component. Their analysis treats the density difference, gravity and interfacial tension together, rather than treating orbit as the only way to reduce gravitational distortion. This is a specific physical analogue, not a reproduction of every feature of spaceflight. Frumkin and Bercovici, fluidic shaping
The paper's capillary-length relation offers a compact way to reason about scale. With the other quantities fixed, reducing the density difference by a factor of one hundred increases that characteristic length by a factor of ten, because the relation involves an inverse square root. That is an illustrative ratio derived from the stated model, not a recipe or a claim that any real liquid pair can be matched perfectly at every temperature.
What makes the example valuable is its causal structure. If the difficulty is a particular competition between body forces and interfacial forces, changing another term in that competition may reproduce part of the desired behavior. The ground experiment need not pretend that the gravitational field has vanished. It needs to specify which consequence of gravity it is counteracting and what additional effects the substitute environment introduces.
A strong development program can use the difference productively. A ground experiment might permit many repetitions of shape formation. A short flight might test whether the same geometric idea works without immersion. A longer orbital experiment might test solidification and subsequent use. The sequence is informative when each stage answers a new question, rather than when all three are counted as repetitions of one sweeping claim.
The terrestrial alternative also matters to eventual value. If an application can obtain the required object through a simpler ground process, the orbital route needs a different advantage to justify its complexity. If the desired object must be created or adjusted where it will be used in space, that is a different comparison. The scientific mechanism and the practical objective should be stated together.
A process has more than one clock
In a separate study first posted in December 2022, Luria and colleagues described parabolic-flight experiments forming liquid lenses and measuring them in situ through imaging and wavefront sensing. The work demonstrated liquid optics during limited low-gravity intervals; the lenses were not thereby shown to remain usable after ordinary gravity returned. The distinction between observing a temporary liquid shape and producing a stable finished component is central to reading the result. Luria and colleagues, parabolic-flight study
A process can contain a fast event and a slow event that require different experiments. Imagine a material that reaches the desired shape after ten seconds but needs ten minutes to become mechanically stable. A twenty-second observation window could examine the first event and the beginning of the second. It could not directly establish the full ten-minute outcome under uninterrupted conditions.
Repeating the twenty-second window thirty times would not necessarily solve that problem. Thirty repetitions of an interrupted process are not automatically equivalent to one continuous ten-minute process. If the material retains changes between intervals, the later repetitions begin from different states. If it resets completely, each repetition investigates the short stage again. Either history may be informative, but neither should be silently relabeled as the uninterrupted history.
The same issue arises when a process starts before the low-gravity interval. An experiment must identify what fraction of the relevant transformation occurred before, during and after the interval of interest. Otherwise, a returned object may be assigned to an environment that governed only a small part of its formation.
This is why in-situ observations can be unusually valuable. They can show whether the target shape appeared, when it changed and whether a defect emerged during the proposed mechanism rather than during later recovery. They do not remove the need for final testing. They help connect the final specimen to a specific stage in its history.
The research question is therefore not simply “Can this happen in microgravity?” It may be “Can this stage occur within the available interval?” or “Does the structure persist after the next transition?” Those versions are less dramatic but more useful. They tell the next experiment what remains to be learned.
Removing a flow can remove cooling as well
Jonathan Ericson and colleagues' 2026 accepted manuscript combines orbital observations, parabolic-flight experiments and a thermal model for photopolymer processing. It examines heat generated during curing and the consequences of reduced natural convection, with laboratory comparisons and model limitations stated in the paper. Some ISS observations overlap the lens program described earlier; this is not an independent replication by a separate production team. Its additional contribution concerns thermal behavior and modeling, not a universal guarantee of defect-free manufacturing. Ericson and colleagues, thermal-behavior study
The broader engineering point is that a mechanism can have more than one role. A flow that disturbs a liquid's shape may also help carry heat away. Suppressing it can improve one objective while making another harder. “Less convection” is therefore not a complete design recommendation. Its value depends on what the process needs transported, and when.
Geometry makes this interaction especially important when a demonstration is enlarged. Consider two idealized cubes made of the same material, one with twice the edge length of the other. The larger cube has eight times the volume and four times the surface area. Its surface-area-to-volume ratio is half as large. Those are geometric facts, not a prediction of a particular polymer's temperature.
If an imagined reaction releases the same energy per unit volume in both cubes, the larger cube releases eight times as much total energy. The ability to remove that energy cannot be inferred merely by noticing that its surface is bigger. A complete thermal comparison needs the relevant boundaries and transport mechanisms. The ratio calculation explains why copying a small demonstration at a larger size is a new question rather than a neutral enlargement.
Nor is a temperature measured at one location necessarily the temperature everywhere that matters. In an imagined sample, the surface could be within a desired range while an interior region follows a different history. An average could hide both. A report that explains the measurement location and what the model predicts elsewhere is more useful than one that gives a single temperature without a spatial boundary.
This is not a set of operating instructions. It is a reason to treat shape formation, chemical transformation and heat removal as a coupled problem. A material does not stop obeying thermodynamics when a force that was convenient on Earth becomes less effective in orbit.
A different cooling history is not a nuisance detail
Stephen Wilke and colleagues' March 6, 2024 study compared neodymium-titanate melt processing in an orbital electrostatic levitator with terrestrial aerodynamic levitation. It examined thermal behavior and characterized glassy and crystalline products through several methods. The glasses had broadly similar atomic structures, while crystalline products differed substantially; the authors also considered composition and processing differences. The comparison is not a perfectly isolated gravity switch: the apparatus and cooling environment differ, and those differences are part of the interpretation. Wilke and colleagues, neodymium-titanate study
This kind of result resists a one-dimensional ranking. An object may differ in its large-scale appearance while retaining a similar local atomic arrangement. Another may have similar outward dimensions and a different internal organization. The technique used to inspect it determines which distinction becomes visible.
Imagine two samples that begin and end at the same temperatures but spend different amounts of time in an intermediate range. Their endpoints alone do not describe their histories. One might pass quickly through the range; the other might linger. If the transformation of interest occurs there, the time spent between the endpoints may matter more than either endpoint itself.
A comparison that reports only “heated and cooled” could therefore miss the variable most relevant to the resulting structure. The appropriate record may be a time-dependent thermal history, accompanied by the measurement uncertainty and the method used to infer temperature. The example is qualitative because the necessary transformation rates depend on the actual material; inventing a universal temperature schedule would obscure the point.
Composition creates another interpretive branch. If two nominally identical samples differ slightly in what they contain, the final structural difference may not be explained by gravity alone. The question becomes whether composition was measured, controlled, changed during processing or inferred indirectly. A nominal recipe and a measured final composition are not always the same piece of evidence.
These distinctions do not make comparative experiments futile. They make the claim more precise. A study can establish how two real processing routes differ while leaving some causal contributions unresolved. That is more informative than forcing the result into either “space wins” or “space makes no difference.” The material's path through its environment is the object of study.
Fiber length and optical loss are separate achievements
NASA's March 25, 2024 account of an orbital optical-fiber investigation described substantial produced lengths while explicitly saying that returned-fiber quality analysis was still needed at that point. The important temporal qualification is “at that point”: this article does not infer that the analysis remains unfinished today. The historical account separates a manufacturing-length milestone from a later evaluation of optical quality. They are complementary results, not synonyms. NASA's optical-fiber production account
For an original numerical illustration, suppose an imaginary fiber transmits ninety percent of the light entering each identical segment, with all other losses excluded. Two segments transmit eighty-one percent; ten transmit about thirty-five percent. The remaining fraction is obtained by multiplying the segment transmissions, not by subtracting ten percentage points ten times. These invented numbers are not ZBLAN measurements or a specification for any product.
The calculation explains why a short specimen's promising appearance does not settle the performance of a much longer length. It also shows why the measurement must name its wavelength, length and boundaries. A reported transmission fraction without those conditions may be impossible to compare with another result. Adding connectors or bends to an application can introduce a different test from examining a straight material specimen.
Ayush Subedi and colleagues' July 6, 2026 study investigated ZBLAN glass under controlled heating with and without mechanical vibration. It observed changes in crystallization behavior and characterized the resulting material. This was a terrestrial processing study, not an orbital fiber-transmission trial. It identifies vibration as a variable worth examining; it does not establish a flight-produced attenuation value or prove that all orbital vibration is harmful. Subedi and colleagues, ZBLAN vibration study
A useful fiber evaluation would therefore avoid selecting its metric after seeing which one looks best. Length, continuity, optical behavior and consistency along the specimen answer different questions. A manufacturing route that improves one might still require work on another. A report can celebrate a long draw without implying that a finished communication system has been qualified.
The same logic applies to sampling. Testing a few convenient locations may reveal a local property. It does not automatically characterize every metre. If the process changed during production, position along the fiber becomes part of the evidence. A continuous object can contain a time history of its manufacture, and the evaluation should preserve that connection.
A crystal is a record of transport
Arayik Martirosyan and colleagues' 2022 study compared crystallization in microgravity with unit-gravity controls for three proteins, using fluorescently labeled aggregates to examine their incorporation. The measurements supported reduced aggregate incorporation under the tested microgravity conditions. The result concerns a specified transport and crystallization problem; it is not evidence that every protein, drug or industrial crystal becomes better in orbit. The accessible publisher PDF supports the bounded comparison without requiring a clinical inference. Martirosyan and colleagues, aggregate-transport study
A useful way to think about crystal growth is as a question of what reaches a growing surface and when. The final object contains a history of that supply. If the surrounding material changes over time, the growth environment at the surface need not match the bulk mixture far away. Measuring only the starting mixture may miss the conditions under which later parts of the crystal formed.
An elementary diffusion model illustrates the time-scale issue without reproducing a particular experiment. For a characteristic diffusion distance proportional to the square root of time, reaching twice the distance requires four times the time when the diffusion coefficient is fixed. Reaching ten times the distance requires one hundred times the time. This is a scaling example, not a prediction for a named protein or a recommendation for crystal-growth conditions.
The consequence for interpretation is that “more time” and “more material” are not equivalent changes. A larger experimental volume may introduce longer transport distances. A short experiment in a small volume cannot automatically determine what happens in a larger one, even when the starting concentration is identical. The relevant comparison needs geometry and time as well as composition.
It is also important not to turn an explanation for one improvement into a claim that slower is always better. A process may have competing objectives: produce a usable structure, finish before a deadline, avoid unwanted changes during storage and yield enough material for the intended test. The best balance depends on the application and must be measured rather than inferred from a slogan about gentle growth.
For structural research, a small number of unusually informative crystals can be valuable. For bulk manufacture, reproducible output may dominate. Those are different uses of the same physical phenomenon, and they require different evidence before either can be called successful.
The strongest control may be an improved Earth process
José Gavira and colleagues' January 25, 2020 study made a particularly important comparison: crystals grown under reduced convection in space versus crystals grown in agarose gels on Earth, using matched counterdiffusion setups and attention to other conditions. For their studied proteins and structural-crystallography indicators, they did not find an obvious quality separation favoring the space condition. This is not proof that microgravity never helps crystallization. It shows why a ground process designed to address the same mechanism can be a more demanding comparator than an arbitrary terrestrial baseline. Gavira and colleagues, controlled comparison
There are at least two legitimate questions here. One asks what changes when a particular process is moved to microgravity with as much else as possible held constant. Another asks which available process produces the most useful output for a specific purpose. The first is a causal comparison. The second is a practical comparison between alternatives. They can require different controls and need not produce the same ranking.
An original imaginary experiment makes the distinction concrete. Suppose a conventional Earth process produces a quality score of forty, an improved Earth process produces seventy and an orbital process produces seventy-five. All scores are invented and their scale is arbitrary. Comparing seventy-five with forty suggests a large advantage. Comparing seventy-five with seventy asks whether the remaining difference justifies the added complexity for the intended use.
Neither comparison should replace the other. The first might reveal a scientifically interesting change from a baseline. The second might be the relevant choice for a purchaser or mission designer. The problem arises when a report uses the weaker baseline to imply superiority over all terrestrial alternatives.
A further complication is that the improved Earth process may introduce a different material or boundary. Then the comparison is not a pure gravity experiment, but it may still be the correct application comparison. Research can identify the mechanism and practical evaluation can choose among complete processes. Treating these as separate tasks makes the evidence more useful.
This perspective protects the value of a negative or small difference. If a ground method achieves the desired result, that is not a failed space experiment; it may be an important finding about the governing mechanism. Conversely, if a meaningful gap persists against a strong ground comparator, the case for the orbital route becomes more persuasive. The strength of the control determines how much the conclusion can carry.
A measurement comparison can also be smaller than its unresolved uncertainty. Consider an invented dimensional test in which a ground specimen has a reported deviation of ten units and a flight specimen eight units. Suppose, purely for illustration, that each instrument reading has a defensible hard error bound of two units. The possible deviations are then eight through twelve for the first specimen and six through ten for the second. The observed two-unit advantage does not establish that the second specimen is truly closer to the target in every case consistent with those bounds. The first could be eight and the second ten. These intervals are stipulated error bounds, not calculated statistical confidence intervals or measurements of actual optics.
The purpose of the example is not to demand zero uncertainty. It is to ask whether a claimed improvement is resolved by the test being used. Repeated readings might expose some variability while leaving a shared calibration offset untouched. If both specimens are measured by the same instrument, a common offset may affect their difference differently from two unrelated offsets. The analysis needs that relationship rather than an automatic rule that every uncertainty should be added, subtracted or ignored.
A proposed comparison could conceal specimen origin from the person assigning a subjective surface-quality score, retain the raw instrument readings and specify the acceptance boundary before opening the labels. That would not make every result conclusive, but it would separate the material difference from avoidable changes in how it is judged. It is a suggested evaluation design, not a claim about procedures completed in the cited studies.
Order at one scale does not certify the whole object
Qian Lei and colleagues reported ISS experiments on colloidal assembly in an author manuscript revised in July 2024. Using confocal microscopy, they examined the formation of large face-centered-cubic structures from suspended particles. The study points toward possible optical-material applications, but observing ordered structure is not the same as demonstrating a manufactured optical device with qualified performance. The manuscript's experimental result and its suggested applications should remain separate. Lei and colleagues, colloidal crystals
A colloidal crystal is not interchangeable with a protein crystal or a glass merely because all three appear in a story about materials. Their constituents, structures and useful properties differ. What connects them here is the demand to relate a measured feature to an intended function without skipping the intermediate steps.
Consider an imaginary sample inspected in ten small volumes. If those volumes show the desired local order, the observation is strong evidence about the inspected regions. Whether it supports a claim about the complete sample depends on the sampling scheme and on what variation could exist between those regions. Ten deliberately selected clear regions are not the same evidence as ten locations selected before the sample was examined.
Scale matters in the measurement as well. An instrument may resolve one type of defect while missing another. An image can be excellent for showing a local arrangement and insufficient for assessing a large-scale distortion. A claim of “no observed defects” should therefore retain the observation's spatial extent and resolution rather than becoming an unlimited claim of perfection.
This is not a demand that every experiment prove every possible property. It is a demand that the noun attached to success be specific. Demonstrating self-assembly, characterizing an ordered region and producing a functional device are each worthwhile accomplishments. They become confusing only when the language makes them sound like the same completed task.
A useful progression would connect the structural measurement to a functional test, then examine whether repeated objects reproduce both. That is a proposed evidence sequence, not a statement that the cited team has already completed it. The next important result may be the connection between two measurements, rather than a larger photograph of the original phenomenon.
Count independent runs, not only attractive specimens
The evidence needed for a manufacturing claim changes as the claim moves from possibility to repeatability. A single successful specimen can demonstrate that an outcome is possible under its recorded conditions. It cannot, by itself, establish how often the outcome occurs. That second question requires a denominator that includes the attempts which did not yield a usable specimen.
Imagine a fictional experiment with ten processing runs, each producing ten pieces. Nine runs produce no acceptable pieces; one produces ten. There are ten acceptable pieces in a set of one hundred, but only one successful run in ten. Reporting ten successes without explaining their common origin would make the evidence look more independent than it is.
Now compare a second fictional process in which every run produces one acceptable piece. Its total yield is also ten pieces out of one hundred, yet the distribution across runs is different. Depending on the application, that difference could matter for scheduling, diagnosis and the confidence placed in a future run. The same total can conceal very different forms of consistency.
Within-run measurements remain useful. Repeated observations can reveal variation across a specimen or the precision of an instrument. The problem is treating them as though they were new, independent manufacturing histories. A hundred images of one object do not provide a hundred independent tests of whether the process can make that object again.
Batch identity should therefore travel with the sample record. If several objects share a feedstock batch, processing chamber or return container, those shared conditions may explain part of their similarity. An analysis that preserves the grouping can ask where variation enters. An analysis that erases it may attribute every difference to the most dramatic label: Earth or space.
The same principle applies when multiple papers describe a research program. Different analyses of shared samples can add genuine knowledge without multiplying the number of independent experiments. The literature becomes more intelligible when it identifies which observations are new, which are reexamined and which are predictions awaiting a separate test.
The return journey creates an interpretive boundary
For an object intended for use on Earth, returning it is part of the manufacturing proposition. For an object intended to remain in space, return may be a research convenience rather than its future operating environment. These two purposes should not be confused when evaluating a specimen after recovery.
A simple causal diagram helps: formation precedes storage, storage precedes transport, and transport precedes the final measurement. If the measurement finds a defect, several stages may be plausible contributors. Without an observation earlier in the sequence, it may be impossible to determine exactly when the defect appeared. That uncertainty does not invalidate the final observation; it limits the explanation attached to it.
An imagined comparison could use an in-situ image, an immediately post-processing measurement and a later ground measurement. Agreement would support stability for the observed properties across those stages. Disagreement would identify a change to investigate. Neither outcome should be interpreted more broadly than the methods permit: an unchanged visible outline does not establish unchanged internal structure.
Controls can also have histories. A ground specimen held at one temperature for a short period is not automatically comparable to a flight specimen stored longer before measurement. If the goal is to isolate formation conditions, later differences need attention. If the goal is to compare complete delivery routes, those differences may properly remain part of the treatment being compared.
The useful choice depends on the question. One experiment may ask whether microgravity changes a mechanism. Another may ask whether the entire orbital route delivers a better usable object. Both are legitimate, but the second includes burdens that the first may deliberately hold outside its boundary.
That distinction is especially important for fragile or metastable structures. Observing that something can exist during a particular experiment is not the same as showing it can survive the sequence required by an application. A complete account states whether stability was tested, inferred or left for later work. The wording should not allow an untested transition to disappear between the laboratory image and the proposed product.
Scale-up is a change in the question
A manufacturing process does not become routine simply because the object has been made larger. Scale can refer to the size of one object, the number made per run, the number of repeated runs, the duration of autonomous operation or the amount of useful output delivered. These are different axes of development.
For an original yield calculation, suppose a fictional process converts a hundred units of feedstock into eighty units of returned material, of which half meets the intended specification. Its qualified output is forty units, not eighty. If a revised process returns seventy units and eighty percent qualifies, the qualified output rises to fifty-six units despite the smaller return mass. Neither scenario describes an actual company or mission.
The arithmetic illustrates why total production can be the wrong headline for an application. A user needs the material that meets a stated requirement, not merely the material that exists. The requirement itself should be fixed before inspecting the results; otherwise, a process can appear successful by redefining its output around whichever property happened to be strongest.
The resource boundary matters too. A laboratory demonstration might rely on skilled intervention that is appropriate for discovering a mechanism. A proposed routine process must state whether those interventions remain available. Automation is not established by omitting the human decisions from the description. It is established by showing which decisions the system can execute and under what limits.
This does not diminish early experiments. Discovery and production have different jobs. A researcher may deliberately explore an unstable or inconvenient regime because it reveals important physics. An operator may prefer a less spectacular but repeatable outcome. Requiring a discovery experiment to prove a business case would be unfair; treating it as though it already had would be equally misleading.
The right next experiment follows the remaining uncertainty. If geometry is the limiting question, make a geometry test. If variability dominates, repeat independent runs. If recovery is uncertain, measure across the recovery boundary. A general promise of future “scale” is less useful than a concrete statement of which of these questions is being addressed next.
What the word “better” must contain
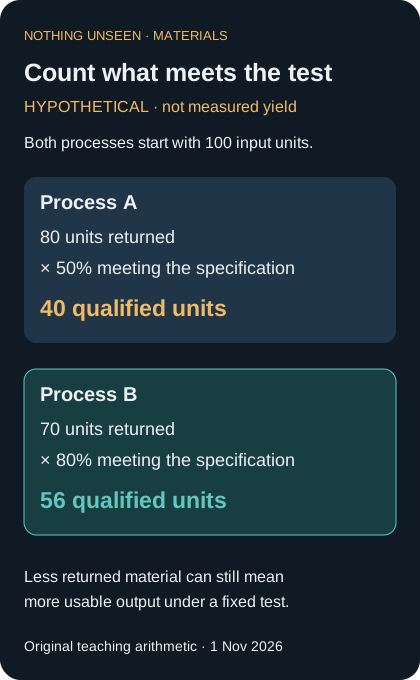
Fictional comparison, not measured manufacturing yield. Both routes start with 100 input units and use a fixed acceptance specification; returned material and qualified output are different quantities.
There is no single materials leaderboard on which Earth and orbit can be placed. The relevant comparison depends on a material, a process, an application and a measurement. A change that improves one of those relationships may weaken another or make no useful difference at all.
The evidence reviewed here supports a more exact way of reading the field. Identify the physical mechanism the experiment changes. Separate the moment of formation from solidification, storage and use. Name the property that improved, and compare it with an appropriate terrestrial alternative. Preserve the failed attempts and the uncertainty about stages that were not observed.
Most importantly, keep the scientific result distinct from the proposed consequence. A formation mechanism can be demonstrated before a reliable product exists. A manufacturing-length milestone can precede a quality assessment. An ordered structure can motivate an application without constituting the application. Those boundaries let a reader recognize genuine progress without borrowing certainty from the future.
An orbital laboratory is a remarkable place to make a material because it changes some of the conditions that Earth-based processes take for granted. It does not suspend the need for thermal management, measurement, causal controls or repeatability. The factory may be falling around the planet. The material still records what happened to it, and the evidence has to be good enough to read that record.
Evidence and access note
Prepared and accessed 1 November 2026. Eleven distinct primary research/institutional works and one supplementary NASA physics explainer are cited; shared experiments and manuscript versions are not counted as independent replications. The July 2026 opening concerns April 2022 experiments. Two publisher PDFs are explicitly accepted article-in-press versions; source-route failures and successful public alternatives are documented separately. No clinical treatment, commercial yield, routine service or universal material-quality claim is inferred. Hypothetical examples are original explanatory comparisons, not experimental data or manufacturing protocols.